Georeactor Blog
RSS FeedClustering Prion Proteins
Recently I collected ~46,000 sequences labeled 'prion' on the NCBI website. In this post I use gLM2 embeddings to try and group the dataset into meaningful clusters.
In my initial post I noticed ~200 sequences have the same amino acid sequence, ~400 are human, and the dataset includes proteins which are prion-like or inhibit prions... just anything which was associated with prions. I'd like to see clusters like that.
Right away the script removed 7 sequences which were a little longer than the model allowed, but nothing as bad as the complete genomes which came through before my filtering in my previous work. I decided to review if those belong in the dataset. A rat protein was linked to a paper with "prion" in the title, but I couldn't tell how relevant this specific protein was. There was one long sequence (XP_072180894.1) where I can't figure out what the prion connection might be? I would rate this sample as 'OK-ish'.
The clustering diagram essentially confirms there are a few large groups, and most are disconnected:
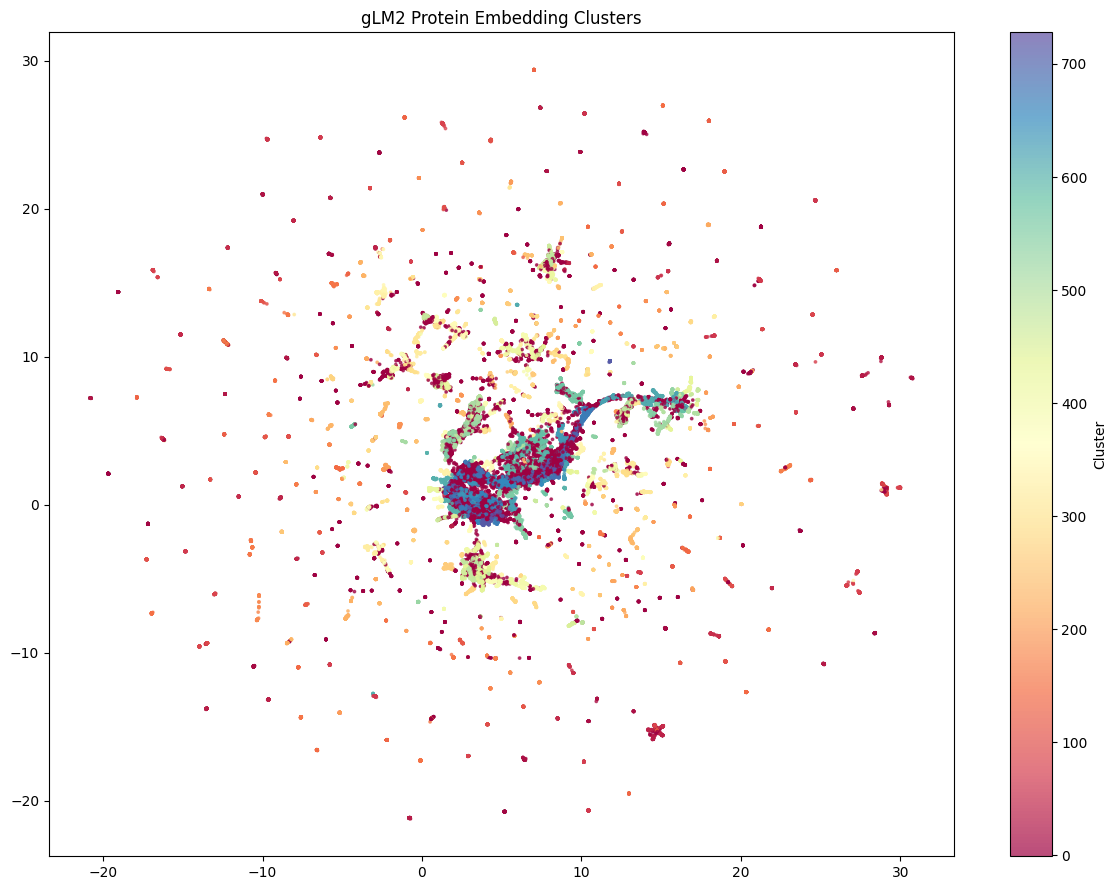
I asked ChatGPT for some code to pull descriptions of proteins in the most popular clusters, and then manually investigated any commonality:
- 1, Most popular: prion inhibition
- 2, unusual variety?
- 3, "prion-like"
- 4, "shadow of prion protein"
- 5, "prion formation protein"
- 6, "domain-containing protein"
- 7, proteins from a wheat fungus Parastagonospora nodorum
- 8, prion-inhibition
- 9, "shadow of prion protein 2"
- 10, human prion protein
Somewhat related - there is a recent article that frequency of a specific genetic sequence / mutation rate is a bad measure for importance of that sequence: https://journals.plos.org/plosbiology/article?id=10.1371/journal.pbio.3004089
